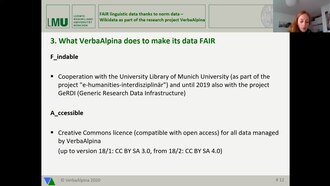
FAIR-linguistic-data-thanks-to-norm-data-Wikidata-as-part-of-the-research-project-VerbaAlpina
ChMutter
Make a clip
CC BY-SA 4.0 · ChMutter
Up to 60 seconds, at most the picture size of the copy it is cut from. The clip carries the title, the credit, the licence and a link back here. It is made in this browser, and nothing is sent to this site.
Start
Length
Or send the moment itself: https://invisiblenetwork.ai/watch/archive/commons/93016081?play=1&t=0
Parts
About
This presentation illustrates in more detail how the German research project VerbaAlpina generates norm data by itself and integrates norm data of other institutions, in particular Wikidata, in order to label linguistic data according to the FAIR principles.
Human-made No record of this work says a model made it. What this means.
More from Wikimedia Commons
 Short
Making a silver chain
 Short
Jennifer Doudna Nobel Prize medal presentation
 Short
¿Qué es Wikipedia?
 Short
Wie entstehen Fossilien (CC by 4.0)
 Short
Rudy Mancuso & Maia Mitchell - Magic (Official Music Video)
 Documentary
Die wichtigsten Klimafaktoren (ZDF, Terra X) 720p 50FPS
 Short
Curiosity's Seven Minutes of Terror
 Short
Wikilovesmonuments.org
 Short
Wikipedia - FactsMatter2016
 Short
President Obama on Death of Osama bin Laden no watermark
 Short
Cassini's Grand Finale
 Cartoon