Opening the book…
Let's begin by trying to find the most "typical" value of a data set.
Note that we just used the word "typical" although in many cases you might think of using the word "average." We need to be careful with the word "average" as it means different things to different people in different contexts. One of the most common uses of the word "average" is what mathematicians and statisticians call the arithmetic mean, or just plain old mean for short. "Arithmetic mean" sounds rather fancy, but you have likely calculated a mean many times without realizing it; the mean is what most people think of when they use the word "average."
The mean of a set of data is the sum of the data values divided by the number of values.
The interpretation of the mean is based on the definition. Let's see some examples to explore how to compute and interpret the mean.
Marci’s exam scores for her last math class were: 79, 86, 82, 94. Marci's final course grade is calculated based on the mean of these four exams. What would be Marci's final course grade? What is the interpretation of the mean?
Solution
\[\frac{79+86+82+94}{4}=85.25. \nonumber \]
Typically we round means to one more decimal place than the original data had. In this case, we would round 85.25 to 85.3. In a traditional US system, Marci would expect a B in the class.
Interpretation: If we equally distribute all the score points into the four exams, each exam will account for approximately 85.25 points.
The number of touchdown (TD) passes thrown by each of the 31 teams in the National Football League in the 2000 season are shown below.
37 33 33 32 29
28 28 23 22 22
22 21 21 21 20
20 19 19 18 18
18 18 16 15 14
14 14 12 12 9
6
Calculate and interpret the mean.
Solution
Adding these values, we get 634 total TDs. Dividing by 31, the number of data values, we get \(\frac{634}{31} = 20.4516\). It would be appropriate to round this to 20.5.
It would be most correct for us to report that “The mean number of touchdown passes thrown in the NFL in the 2000 season was 20.5 passes,” but it is not uncommon to see the more casual word “average” used in place of “mean.
Interpretation: If we equally distribute the number of touchdowns among the 31 teams, each team will get approximately 20.5 points.
Discussion:
The price of a jar of peanut butter at 5 stores was: $3.29, $3.59, $3.79, $3.75, and $3.99.
- Find the mean price.
- What is the unit?
- Write an interpretation for your value.
The one hundred families in a particular neighborhood are asked their annual household income, to the nearest $5,000. The results are summarized in a frequency table below.
\(\begin{array}{|l|l|}
\hline \textbf { Income (thousands of dollars) } & \textbf { Frequency } \\
\hline 15 & 6 \\
\hline 20 & 8 \\
\hline 25 & 11 \\
\hline 30 & 17 \\
\hline 35 & 19 \\
\hline 40 & 20 \\
\hline 45 & 12 \\
\hline 50 & 7 \\
\hline
\end{array}\)
Calculate and interpret the mean.
Solution
Calculating the mean by hand could get tricky if we try to type in all 100 values:
\[\frac{15 + \cdots + 15 + 20 + \cdots+20 + 25 + \cdots + 25 + \cdots}{100} \nonumber \]
We could calculate this more easily by noticing that adding 15 to itself six times is the same as \(15 \cdot 6=90\). Using this simplification, we get
\[\frac{15 \cdot 6+20 \cdot 8+25 \cdot 11+30 \cdot 17+35 \cdot 19+40 \cdot 20+45 \cdot 12+50 \cdot 7}{100}=\frac{3390}{100}=33.9 \nonumber \]
The mean household income of our sample is 33.9 thousand dollars ($33,900).
Interpretation: If the total amount of money earned by all households is equally split in each of them, each household would get $33,900.
Notice all these values are between $15,000 and $50,000. Having a mean of $33,900 is reasonable. Sometimes, the value of the mean can be biased. This can happen when we have atypical values. In this case, the median can support our analysis.
Extending off the last example, suppose a new family moves into the neighborhood, which has a household income of $5 million (equivalent to $5000 thousand). What is the new value of the mean?
Solution
\[\frac{15 \cdot 6+20 \cdot 8+25 \cdot 11+30 \cdot 17+35 \cdot 19+40 \cdot 20+45 \cdot 12+50 \cdot 7+5000 \cdot 1}{101}=\frac{8390}{101}=83.069 \nonumber \]
While 83.1 thousand dollars ($83,069) is the correct mean household income, it no longer represents a “typical” value.
Imagine the data values on a see-saw or balance scale. The mean is the value that keeps the data in balance, like in the picture below.
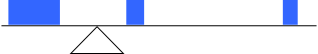
If we graph our household data, the $5 million data value is so far out to the right that the mean has to adjust up to keep things in balance

For this reason, when working with data that have outliers – values far outside the primary grouping – it is common to use a different measure of center, the median.
The median represents the positional center of the data. In other words, about half of the data is above the median and half is below the median. To find the median, begin by listing the data in order from smallest to largest, or largest to smallest.
If the number of data values, \(N\), is odd, then the median is the middle data value. This value can be found by rounding \(\frac{N}{2}\) up to the next whole number.
If the number of data values is even, there is no one middle value, so we find the mean of the two middle values (values \(\frac{N}{2}\) and \(\frac{N}{2} + 1\))
The number of touchdown (TD) passes thrown by each of the 31 teams in the National Football League in the 2000 season are shown below.
37 33 33 32 29
28 28 23 22 22
22 21 21 21 20
20 19 19 18 18
18 18 16 15 14
14 14 12 12 9
6
Calculate and interpret the median.
Solution
We would start by listing the data in order. Luckily, it was already in decreasing order, so we can work with it without needing to reorder it first.
Since there are 31 data values, an odd number, the median will be the middle number, the 16th data value (\frac{31}{2} = 15.5\), round up to 16, leaving 15 values below and 15 above). The 16th data value is 20, so the median number of touchdown passes in the 2000 season was 20 passes. Notice that for this data, the median is fairly close to the mean we calculated earlier, 20.5.
Interpretation: In the 2000 season, about half of the teams had more than 20 touchdown passes and about half had fewer than 20 passes.
Find the median of these quiz scores: 5 10 8 6 4 8 2 5 7 7.
Solution
We start by listing the data in order: 2 4 5 5 6 7 7 8 8 10.
Since there are 10 data values, an even number, there is no one middle number. So we find the mean of the two middle numbers, 6 and 7, and get \(\dfrac{6+7}{2} = 6.5\).
The median quiz score was 6.5.
Interpretation: About half of the quiz scores are below 6.5 and half are above 6.5.
Discussion
The price of a jar of peanut butter at 5 stores was: $3.29, $3.59, $3.79, $3.75, and $3.99. Calculate and interpret the median price. If you were to select the median or the mean to represent this value, which one would you select?
Calculate and interpret the median of the original household problem:
\(\begin{array}{|l|l|}
\hline \textbf { Income (thousands of dollars) } & \textbf { Frequency } \\
\hline 15 & 6 \\
\hline 20 & 8 \\
\hline 25 & 11 \\
\hline 30 & 17 \\
\hline 35 & 19 \\
\hline 40 & 20 \\
\hline 45 & 12 \\
\hline 50 & 7 \\
\hline
\end{array}\)
Solution
Here we have 100 data values. If we didn’t already know that, we could find it by adding the frequencies. Since 100 is an even number, we need to find the mean of the middle two data values -- the 50th and 51st data values. To find these values, we start counting up from the bottom:
\[\begin{array}{ll} \text{There are 6 data values of \$15, so} & \text{Values 1 to } 6 \text{ are \$15 thousand } \\ \text{The next 8 data values are \$20, so } & \text{Values 7 to } (6+8)=14 \text{ are \$20 thousand} \\ \text{The next 11 data values are \$25, so} & \text{ Values 15 to } (14+11)=25 \text{ are \$25 thousand} \\ \text{The next 17 data values are \$30, so} & \text{Values 26 to } (25+17)=42 \text{ are \$30 thousand} \\ \text{The next 19 data values are \$35, so} & \text{Values 43 to } (42+19)=61 \text{ are \$35 thousand} \end{array} \nonumber \]
From this we can tell that values 50 and 51 will be $35 thousand, and the mean of these two values is $35 thousand. The median income in this neighborhood is $35 thousand.
Interpretation: About half of the neighborhood's households have an income of $35,000 or less and about half have more than or equal to $35,000.
Discussion:
If we add in the new neighbor with a $5 million household income, then there will be 101 data values, and the 51st value will be the median. What would be the median? If you were to select the median or the mean to represent the household income of this neighborhood, would you choose the mean or the median? Explain your rationale.
As we discovered in the last example, the 51st value is $35 thousand. Notice that the new neighbor did not affect the median in this case. The median is not swayed as much by outliers as the mean is.
In addition to the mean and the median, there is one other common measurement of the "typical" value of a data set: the mode.
The mode is the element of the data set that occurs most frequently.
The mode is fairly useless with data like weights or heights where there are a large number of possible values. The mode is most commonly used for categorical data, for which median and mean cannot be computed.
Calculate and interpret the mode of the original household problem:
\(\begin{array}{|l|l|}
\hline \textbf { Income (thousands of dollars) } & \textbf { Frequency } \\
\hline 15 & 6 \\
\hline 20 & 8 \\
\hline 25 & 11 \\
\hline 30 & 17 \\
\hline 35 & 19 \\
\hline 40 & 20 \\
\hline 45 & 12 \\
\hline 50 & 7 \\
\hline
\end{array}\)
Solution
The mode is $40,000.
Interpretation: The most frequent household income is $40,000.
It is possible for a data set to have more than one mode if several categories have the same frequency, or no modes if each every category occurs only once.
Discussion:
Reviewers were asked to rate a product on a scale of 1 to 5. Find
- The mean rating
- The median rating
- The mode rating
\(\begin{array}{|l|l|}
\hline \textbf { Rating } & \textbf { Frequency } \\
\hline 1 & 4 \\
\hline 2 & 8 \\
\hline 3 & 7 \\
\hline 4 & 3 \\
\hline 5 & 1 \\
\hline
\end{array}\)
For the previous discussion, notice that the mean is \(\frac{1 \cdot 4+2 \cdot 8+3 \cdot 7+4 \cdot 3+5 \cdot 1}{23} \approx 2.5\). There are 23 data values, so the median will be the 12th data value. Ratings of 1 are the first 4 values, while a rating of 2 are the next 8 values, so the 12th value will be a rating of 2. The median is 2. The mode is the most frequent rating, which is 2.
This page titled 6.3: Measures of Central Tendency was last modified on Tue, 16 Jun 2026 02:38:04 GMT and is shared under a CC BY-SA 3.0 license and was authored, remixed, and/or curated by David Lippman & Jeff Eldridge (The OpenTextBookStore) via source content that was edited to the style and standards of the LibreTexts platform.
The book could not be loaded just now.